How do you calculate the real cost of an AI task?
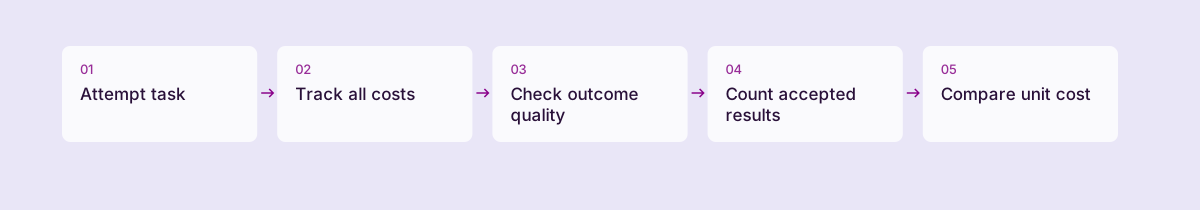
AI cost per completed task divides the full workflow cost by the number of correct, usable outcomes. Include model calls, tools, retries, storage and human review under the same quality standard for each option. Track expensive exceptions as well as the average, then improve the steps that create unnecessary work.
Keep these in mind
- A cheap attempt can become expensive after retries and correction.
- Count successful business outcomes with a defined quality test.
- Track latency and human review alongside direct model cost.
Define completion before comparing models
For invoice capture, completion could require an accepted supplier, date, currency and total. Link those fields to the correct source.
An uploaded file or generated JSON object is not enough. For a task suggestion, completion might mean an accepted owner, scheduled time and deadline.
Write the definition before running a trial. Otherwise one system may look cheaper because it leaves difficult fields blank, while another pays to resolve them.
Both may be useful, but they are not producing the same result. Compare the full job that a person needs finished.
Tokens explain part of the bill
A token is a unit a model uses to process text or other input representations. Providers may price input, cached input, output and tools differently.
OpenAI’s API pricing documentation shows these categories. Use the current documentation for the model and features actually used rather than quoting an old rate.
Long source documents, large tool responses and repeated history can increase usage. A workflow may also call OCR, speech recognition, search or another model. Keep those costs attached to the same business task so a low text-generation bill does not hide expensive preparation work.
An illustrative worksheet
These figures are fictional arithmetic examples, not vendor rates or customer results. Both options attempt 100 comparable tasks. Review labor is converted to a cost using a stated internal assumption.
| Item | Workflow A | Workflow B |
|---|---|---|
| Model and tools | ₹120 | ₹210 |
| Review and corrections | ₹600 | ₹300 |
| Total workflow cost | ₹720 | ₹510 |
| Accepted outcomes | 80 | 90 |
| Cost per accepted outcome | ₹9.00 | ₹5.67 |
Why the cheapest call can lose
Workflow B spends more on models and tools. It uses less review effort and produces more accepted outcomes in this example. That is why its cost per useful result is lower.
The numbers do not establish that a larger model always wins. A smaller model with better inputs and tighter scope may also perform well.
Do not count reviewer time twice if it is already included in another cost line. Keep the conversion method visible so finance and operations can reproduce the comparison. If the staff time cannot be priced meaningfully, report minutes per accepted outcome separately instead of hiding the assumption.
Improve the workflow before chasing a model discount
OpenAI’s prompt-caching guidance describes reuse of repeated prompt content. Caching can change cost and latency, but its benefit depends on actual reusable context and the provider’s rules. Measure the realized usage rather than assuming every request qualifies.
Other improvements are often simpler. Send relevant documents, return necessary fields and stop after a clear failure. Ask a targeted question when repeated attempts leave the same ambiguity unresolved.
Each optimization must preserve quality. A cheaper answer that misses the customer identity is not a successful optimization.
Track the distribution, not just one average
A monthly average can hide a small group of very long tasks. Review the slowest and most expensive examples.
They may contain huge attachments, repeated failures or a loop that should have stopped. Set clear per-task limits and a human route for exceptions.
Evaluate a real invoice-extraction or document-search task with your team. Use the same quality criteria across alternatives and retain the failed examples.
Measure whether the accepted result helps the business at a reasonable cost. Include the effort of people who check and use it.
- Choose one task and define an accepted outcome.
- Run representative and difficult examples.
- Record all calls, tools, retries and review effort.
- Calculate total cost per accepted outcome.
- Inspect expensive outliers before expanding usage.
Common questions
What counts as a completed AI task in a cost comparison?
Define a correct, usable business outcome before the trial, since uploads and generated responses may still need correction. Include all model calls, tools, retries and review effort. Divide total cost by accepted outcomes, applying the same quality criteria throughout.
Why inspect the most expensive tasks as well as the average?
A small number of large documents, repeated retries or unresolved ambiguities can dominate cost and delay. Review those cases for unnecessary context, unclear instructions or a missing stop rule. Keep quality and recovery requirements intact when reducing cost.
Sources & further reading
Primary references for the facts and frameworks discussed. Worked examples and recommendations are Daltn’s own analysis.
- OpenAI API pricing documentation ↗
Provides current model and tool billing categories.
- OpenAI prompt caching ↗
Explains repeated-context caching and usage accounting.
Published by the team building Daltn. Comparisons are first-party analysis, not independent reviews. Our editorial approach.